The compute engine for open data
Open-source, high-performance compute engine for Python, Rust and SQL. Install it in seconds and start transforming data on the machine you already have.
900M+ downloads + 40k+ GitHub stars
Why developers choose Polars
Fast
A multi-threaded, vectorized query engine written in Rust, built for modern hardware and designed for effective parallelism.
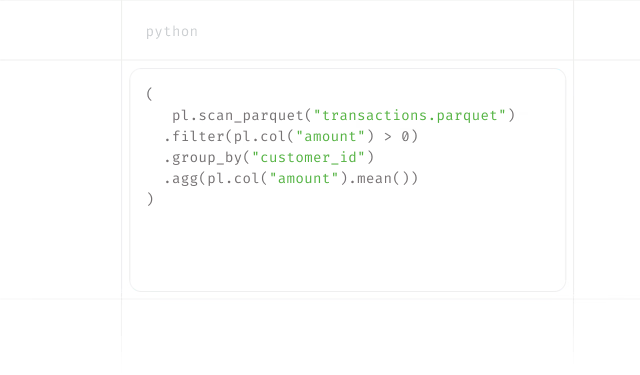
Expressive
A declarative API that lets you state your intent. Polars handles execution order, parallelism, and optimization for you.
Open source
Free forever under the MIT license, driven by an active community of contributors who help shape where Polars goes next.
Extensible
Extend Polars natively with your own I/O and Expression plugins, so custom logic runs at full speed instead of being bolted on top.
The fastest engine on a single machine
A parallel execution engine, SIMD vectorization, and a query optimizer that reorders your operations for you. This results in faster queries, on smaller machines, out of the box.
- Polars34.63 sec
- DuckDB 2.042.12 sec
- DataFusion78.04 sec
- PandasDNF
Write it your way: Python or SQL
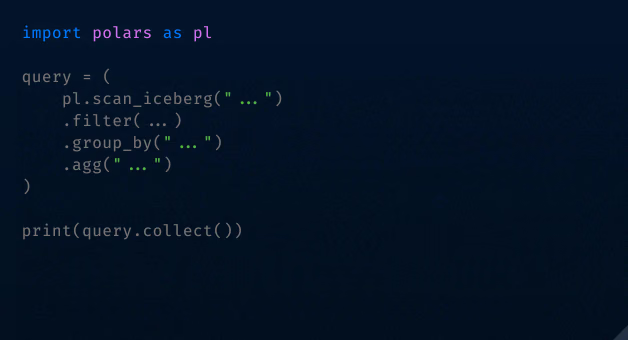
import polars as plcustomers = pl.scan_iceberg(...)query = (pl.scan_iceberg(...).filter(pl.col("order_date").dt.year() == 2025).join(customers, on="customer_id").group_by("region").agg(pl.col("revenue").sum(),pl.len().alias("orders"),).sort("revenue", descending=True))print(query.collect())
How Polars makes your life easier
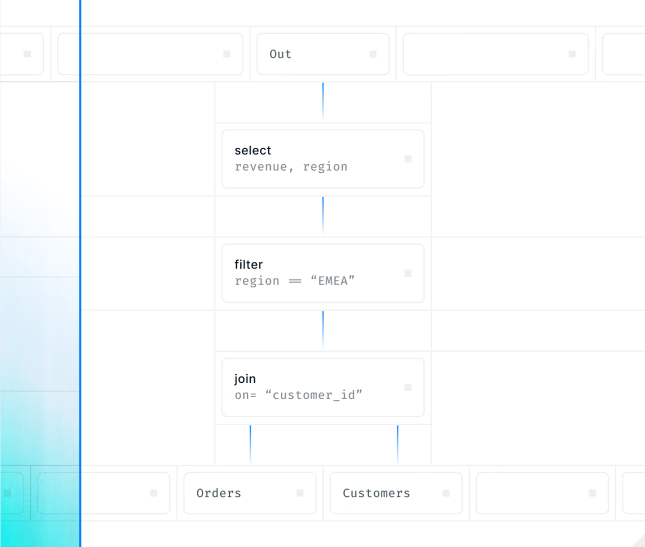
Write queries your way. The optimizer finds the most efficient plan to run them.
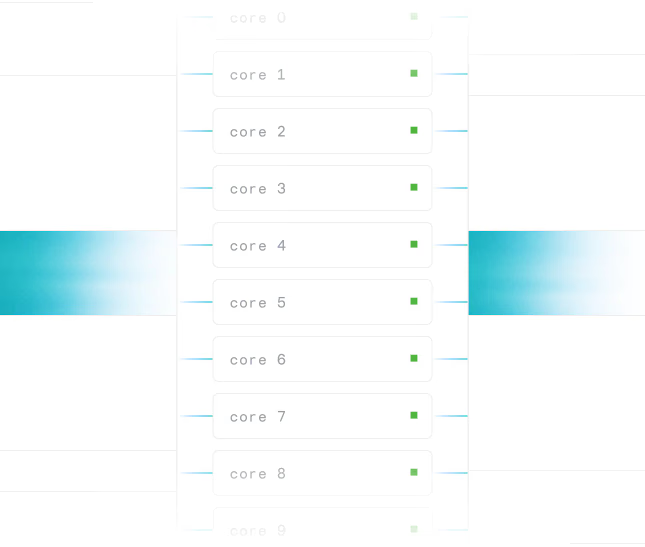
Polars uses all available cores on your machine, with no manual configuration, so it runs as fast as your hardware allows.
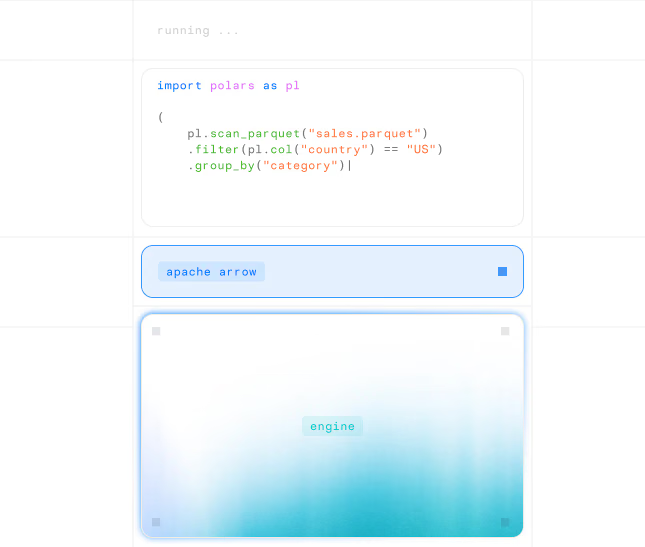
Native integration with the Apache Arrow memory model saves time and memory when you move data between tools.
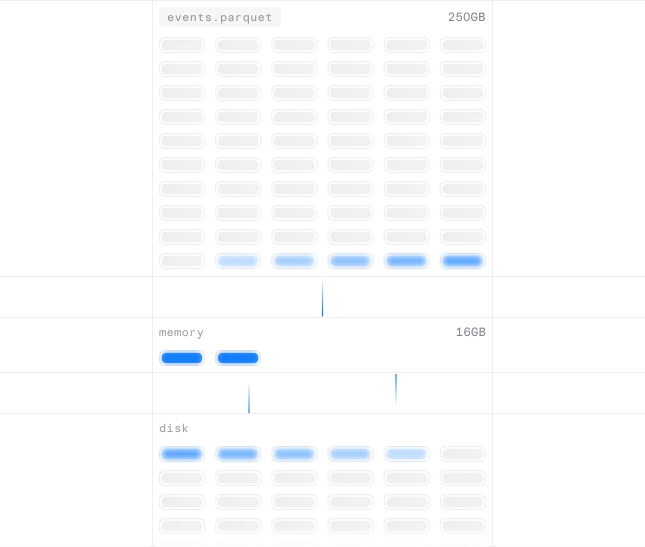
Out-of-core processing spills to disk when memory runs low, so your queries keep running.
Switching to Polars doesn't mean
switching your stack too
Polars is built to work inside even the biggest of data ecosystems. It integrates with Apache Arrow, and can read from all popular file formats and data lakes, including Iceberg and Delta.
Help when it matters most
Enterprise Support goes beyond the open-source community, giving your organization priority support on every issue so your team can keep moving.
Priority on critical bugs
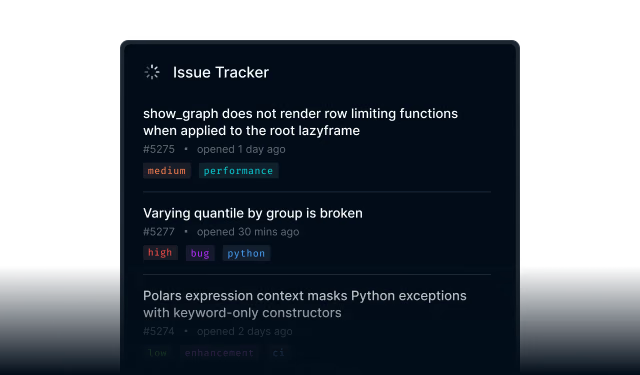
If Polars runs your daily operations, critical bugs you hit get prioritized and resolved fast, cutting your downtime.
Direct communication
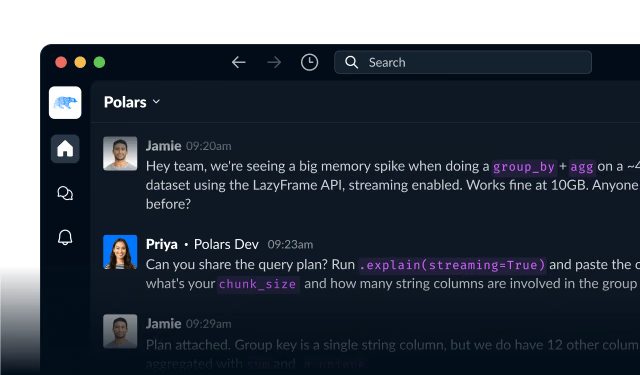
Get a dedicated Slack or Teams channel with the Polars core team to discuss your questions and use cases.
Priority on the roadmap
Feature requests from Enterprise Support customers get priority consideration against our roadmap.
Private consultations
One-on-one sessions with core Polars developers: open discussion, or a deep dive into your specific use case.
Private release channel
Access nightly builds with the newest features via pip install, no need to build or compile it yourself.
Training & coaching
Get your whole team trained directly by the founders of Polars, from the basics to our newest plugins.
Built for the agents you already run
Polars' structured code is exactly what AI reads and writes best. With the official Polars skill, your agents write idiomatic queries that run fast.
- Claude Code
- Codex
- Copilot
- Cursor
Testimonials
“The speedup of Polars compared to pandas is massively noticeable. I generally enjoy writing code that I know is fast.”
Casey H.Machine Learning Engineer- Faster than pandas20x
- Speedup over prior code150x

“Writing fast running code makes my inner child smile. It's like having a fast RC car. And if it's memory efficient too, that RC car will use a lot less batteries.”
Sebastian F.Machine Learning Engineer- Faster train scheduling17x
- Less time to run94%
“It's honestly insane how much of a difference using Polars can and does make. Developing with it is so intuitive. Speed and memory wise, it excels. And with being able to extend it without limits through plugins, Polars is the definitive tool for working with data.”
Isaac R.Data Engineer- Faster financial models10x
- Memory reduction50%
“We made our first breakthrough with the new Polars Streaming Engine in combination with a custom plugin, and the results have been nothing short of incredible.”
Stefan H.Data Scientist- Faster than PySpark jobs7x
Came for the speed,
stayed for the syntax
Learn
 User GuideRead the docs
Your one-stop resource for everything Polars
 AcademyStart learning
Learn Polars at your own pace
Hands-on courses and recommended books that take you from your first query to advanced Polars.
 BlogRead the latest
Releases, benchmarks, and engineering deep-dives from the team building Polars
Scale beyond a single node
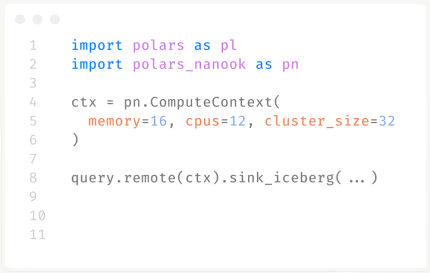
Polars Nanook is the compute platform built around Polars. Run the same code on one machine or across a cluster, see exactly how every query ran, and trace your data from source to result, all inside your own infrastructure.
Frequently asked questions
Polars is open source and MIT-licensed, and it always will be. There's no paid tier of the library itself. Nanook is a separate compute platform for running Polars in production.
You can keep both. Polars integrates with Apache Arrow, so you can convert to and from pandas with zero copy. It slots into the same machine learning and data ingestion libraries you already use, and as Polars support across the ML ecosystem grows, many teams drop pandas altogether.
It depends on the workload, but our published, reproducible benchmarks show gains of up to 50x on common data processing tasks. You're welcome to run them yourself.
Polars is written in Rust and has first-class APIs for Python and Rust, with community-maintained bindings for R, Node.js, Ruby, and Julia.
That's where Polars Nanook comes in. Run the same code across a cluster, with no rewrite, all inside your own infrastructure.