Announcements3 mins
From millions of rows on your laptop to production workloads across a cluster, Polars is the fastest way to work with data.
Trusted by data and AI teams around the world
Write your query once. Run it on your machine or, unchanged, at scale on a cluster or GPUs.
Polars is the fastest open-source compute engine for Python and SQL, free forever under the MIT license. Install it in seconds and transform millions of rows on your own hardware.
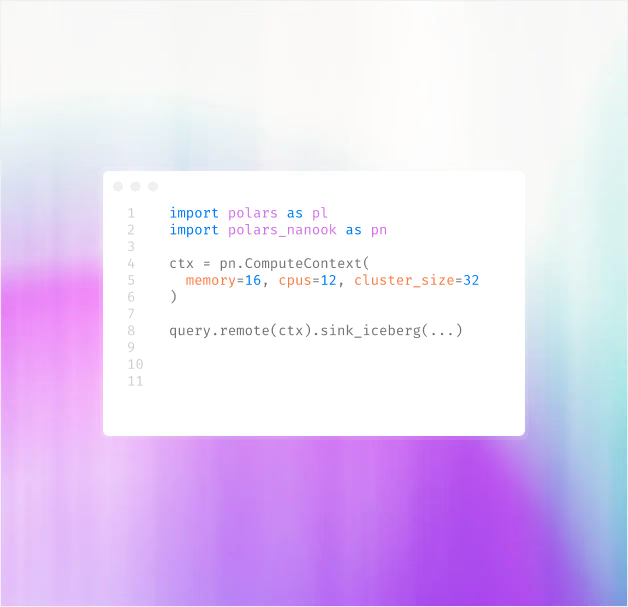
Nanook is the compute platform that speeds up development for your data teams, managing the infrastructure for on-demand, batch and agentic workloads.
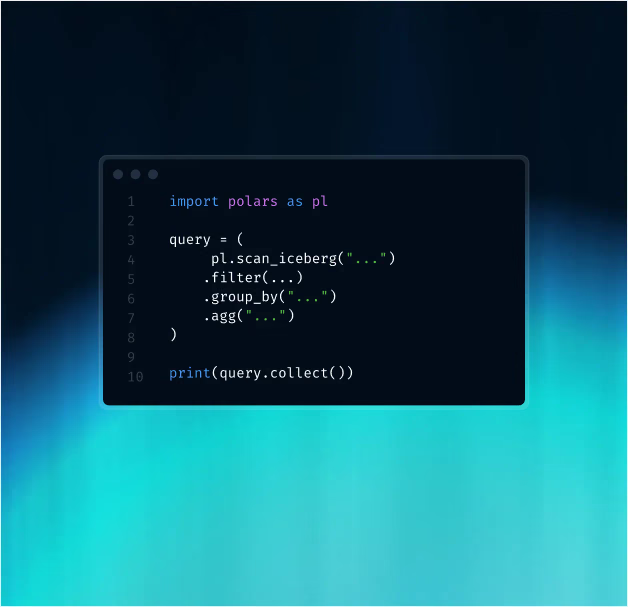
Polars is the fastest open-source compute engine for Python and SQL, free forever under the MIT license. Install it in seconds and transform millions of rows on your own hardware.
Nanook is the compute platform that speeds up development for your data teams, managing the infrastructure for on-demand, batch and agentic workloads.
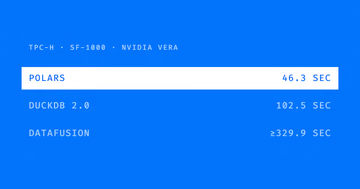
Polars plans every query and strips out the wasted work for you, so you get answers faster on smaller machines. That means lower bills and less time waiting on results.
import polars as plcustomers = pl.scan_iceberg(...)query = (pl.scan_iceberg(...).filter(pl.col("order_date").dt.year() == 2025).join(customers, on="customer_id").group_by("region").agg(pl.col("revenue").sum(),pl.len().alias("orders"),).sort("revenue", descending=True))
Whether you write SQL or DataFrames, your query runs on the same Polars engine, with the same leading performance. If you know pandas, Spark or SQL, it feels familiar from day one, only faster.
Your data never leaves your environment, so your security and compliance teams stay in control. Backed by enterprise support and SLAs for teams that work at the limits.
Polars integrates with the data ecosystem. It reads and writes every data format and source.
“Polars follows most of other DataFrames tool methodologies. Moving from Spark to Polars felt super easy. I would never even try use Pandas again”
“I'm so excited about Polars”
“I don't even remember the last time I used pandas. Polars ftw.”
“I've been using Polars for a while, and it's easily state-of-the-art: fast, lightweight, and super intuitive. Thank you guys, this is huge for the community!”
“Congrats to the polars team! We love Polars at Zalando”
“Polars is a badass. Started using it a while ago. Never looked back.”
“Love your work guys, Just love it.”
“The speedup of Polars compared to Pandas is massively noticeable. I generally enjoy writing code that I know is fast.”
“Most of the time, a Polars job will be completed while we are still waiting for the Spark cluster to coldstart.”